Meta CEO Cites Fair Use in AI Training Data Dispute
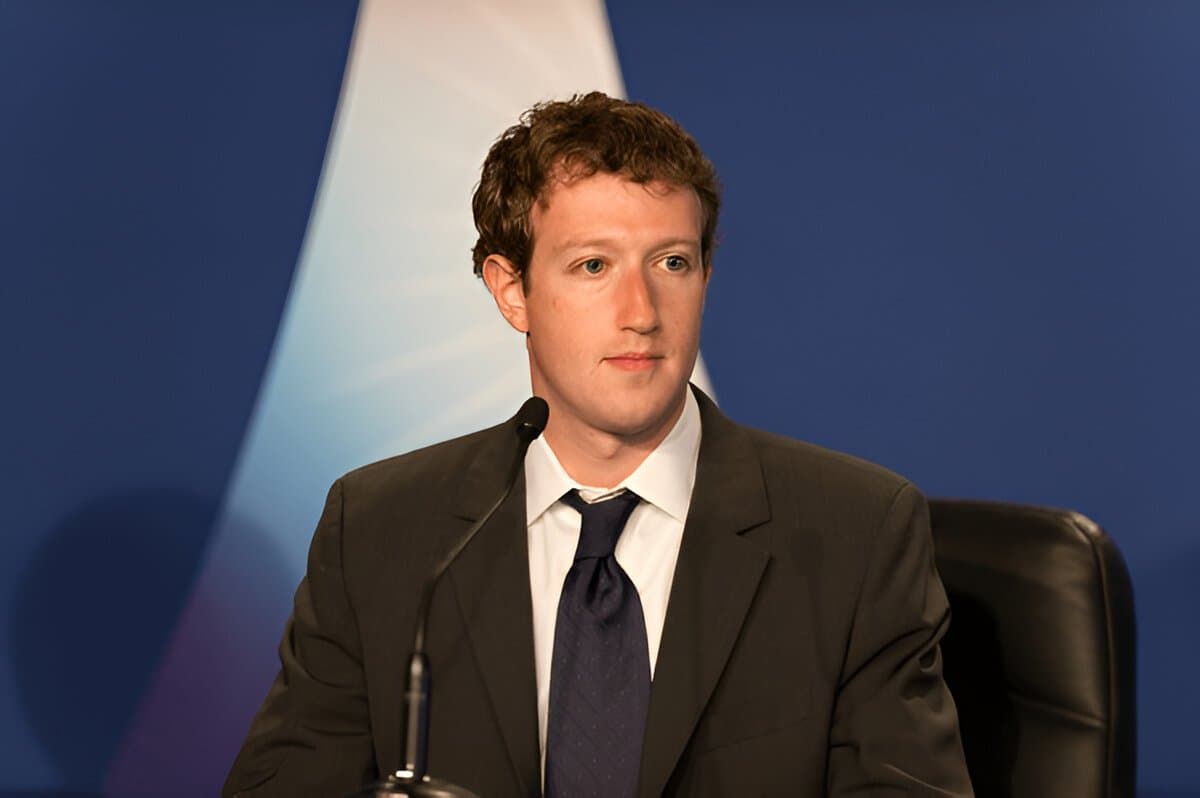
Meta CEO Mark Zuckerberg has drawn parallels to YouTube’s handling of pirated content to defend Meta’s use of copyrighted e-books in training its AI models. Newly released snippets of Zuckerberg’s deposition in the Kadrey v. Meta copyright case shed light on the company’s stance on the contentious issue.
The lawsuit, filed in the U.S. District Court for Northern California, accuses Meta of utilizing copyrighted works from the LibGen data set to train its Llama AI models. LibGen, often referred to as a “pirated content aggregator,” hosts copyrighted materials from major publishers, including Pearson and McGraw Hill. Despite multiple lawsuits, LibGen has continued to provide access to these works.
Zuckerberg’s Argument
During his deposition, Zuckerberg likened Meta’s actions to YouTube’s efforts to address pirated content while maintaining legitimate use. “YouTube may end up hosting some stuff that people pirate for some period of time, but YouTube is trying to take that stuff down,” he said. He also emphasized that the majority of YouTube’s content is licensed and legitimate.
Zuckerberg denied direct knowledge of LibGen but argued against blanket bans on data sets like it. “Would I want to have a policy against people using YouTube because some of the content may be copyrighted? No,” he said, while acknowledging the need for caution when using potentially infringing materials.
New Allegations Against Meta
The plaintiffs, including authors Sarah Silverman and Ta-Nehisi Coates, allege that Meta knowingly trained its AI models on pirated data. Internal Meta communications reportedly described LibGen as a “data set we know to be pirated” and warned that its use could “undermine [Meta’s] negotiating position with regulators.”
According to amended legal filings, Meta allegedly cross-referenced LibGen’s pirated books with copyrighted books available for licensing, using this to decide whether to pursue agreements with publishers. The complaint further claims that Meta researchers attempted to obscure the use of copyrighted materials by inserting “supervised samples” during model fine-tuning. Meta also reportedly used Z-Library, another platform known for hosting pirated content, as recently as April 2024 for training its AI.
Implications for AI and Copyright Law
The Kadrey v. Meta case is one of many lawsuits testing the boundaries of “fair use” in AI training. While AI companies argue that training on copyrighted materials constitutes fair use, copyright holders strongly disagree. The outcome of these cases could have significant implications for AI development and intellectual property law.
As the case unfolds, Meta’s reliance on controversial data sets like LibGen and Z-Library could face intensified scrutiny from courts and regulators. For now, Zuckerberg’s YouTube analogy highlights the complex interplay between innovation and intellectual property rights in the digital age.